Latest Blog Posts
PostgreSQL 19 is Here: Worth the Wait
Posted by Ahsan Hadi in pgEdge on 2026-11-19 at 17:37
PostgreSQL 19 was released today. pgEdge packages for it are available the same day across all of our supported deployments - including Spock, where PG 19 support is already available. I have been testing the release candidates for a few weeks, so here is what I think matters most to DBAs and teams. replaces and , and with the option it rebuilds a bloated table without blocking reads and writes. In my own test, inserts kept running at about 2,000 a second with no failed transactions while a bloated table was rebuilt in under a second. It needs a primary key or replica identity index, and it is not MVCC safe for transactions that started before the swap. Shaun Thomas wrote a blog on the topic - give it a read for more detail. gets the biggest changes for anyone running replicated clusters. Sequences can now be published with and synced with , which removes the manual step from migrations and upgrades. Logical replication can also be turned on without a restart when is replica. Subscriptions get for better conflict detection, and publications can leave tables out with ., autovacuum can now use parallel workers on indexes and ranks tables with a scoring system, so the ones that need it most go first. The and extensions let you steer the planner and keep a plan you trust. The new command gives read-your-writes consistency on standbys. are worth knowing. is faster on text and CSV input, can now write JSON, and lets a load continue past bad values. For monitoring, is now on by default, there is a new view, and the wraparound warning now starts at 100 million transactions instead of 40 million.
Checklist Before You Upgrade to PG19
, check the changed defaults. JIT is now off, is 128, is always on, and in is now , which will break any monitoring built on the old name. A major version upgrade needs pg_upgrade, dump and restore, or logical replication. For pgEdge Enterprise Postgres, the upgrade steps are in our docs. For a Spock cluster, I have written up both approaches using a 17 to 18 upgrade as the example. The[...]Using dbvr with PostgreSQL: From First Datasource to Production Queries
Posted by Dave Stokes on 2026-11-19 at 15:55
What dbvr is, and why use it with PostgreSQL
dbvr lets you define PostgreSQL connections and run SQL from the command line, with no graphical interface. That makes it a fit for servers, containers, and pipelines where a desktop database tool cannot run.
DBeaver Corporation announced dbvr on March 26, 2026 as a standalone CLI built on the same multi-database engine as the DBeaver desktop products. It can:
- Run SQL queries and scripts from saved or inline connection settings, with no interactive login.
- Run on locked-down servers, inside containers, and over SSH on remote hosts.
- Authenticate natively to AWS, GCP, and Azure databases.
- Export query results to S3, Google Cloud, or Azure storage.
- Plug into CI/CD pipelines for database checks and backup/restore validation.
The announcement lists the commercial edition as an annual per-machine subscription with a 14-day trial. DBeaver's 26.1 release post also introduced dbvr Community, a free edition under the Apache License 2.0.
This post covers three steps: creating a PostgreSQL datasource, running queries, and using dbvr for production queries.
You will want to scan the documentation, and the code is available in all the popular package formats.
Creating a PostgreSQL datasource
In dbvr, a datasource is a saved, named connection, so later commands can refer to it by name instead of repeating host and credentials. You create one with the datasource create command, using the postgres-jdbc driver.
Below I am using the gold ol' DVD Rental database on a local server
$dbvr datasource create --driver=postgres-jdbc --name=dvdrental --host=localhost --port=5432 --user=stoker --password=Secr3t --database=dvdrental
postgres-jdbc-1a1f47126cc-2a49d7ea462459bf
$dbvr datasource list
ID NAME DRIVER postgres-jdbc-1a1f47126cc-2a49d7ea462459bf dvdrental postgres-jdbc
Running queries
The sql command runs a query or a whole script against a datasource and
pg_clickhouse 0.11.1: Now with pgvector, UPDATE, DELETE pushdown
Posted by David Wheeler in ClickHouse on 2026-11-19 at 11:52
Don't let the minor version increment fool you: pg_clickhouse v0.11.1, released last week, delivers a slew of improvements and bug fixes, including UPDATE, DELETE, TRUNCATE, and pgvector search pushdown.
pgvector type mapping
Let's start with the latter: pgvector type mapping. Given this ClickHouse table:
CALL clickhouse_perform('ch_server', $$ CREATE TABLE items ( id Int32, category String, v Array(Float32) ) ENGINE = MergeTree ORDER BY (id); $$);
Your biggest tenant runs someone else's plan
Posted by Radim Marek on 2026-11-19 at 11:30
This one started with RegreSQL. Since The tests passed. The plan didn't. I've been loading production statistics into empty databases to see how much the plans alone can tell about a real workload. One paginated endpoint in a multi-tenant app wouldn't line up. Its plan was cheap, a cost of a few hundred and an estimate of one row, while pg_stat_statements in production had the same query reading thousands of buffers per call to return about eight rows.
RegreSQL compares plans by cost, and so do I. The first thing my eyes go to in a plan is the cost on the top line: small number, cheap query, move on. This query's cost couldn't see its own problem, so before deciding what RegreSQL should do about it I rebuilt the case on a synthetic schema where every row can be accounted for. Two ordinary things cause it, one tenant much bigger than the others and a query sent as a prepared statement, and between them PostgreSQL ends up planning the big tenant's query from the small tenants' runs and keeping that plan for as long as the connection lives.
Everything was captured on PostgreSQL 18.7 (the postgres:18 image) with pageinspect. The scripts are setup.sql, query.sql, late.sql and experiments.sql, which replays every plan here. setup.sql doesn't seed random(), so your week of site 1 won't be exactly 1,983 readings, but every count below is arithmetic you can redo on your own number (each reading costs the generic plan ten lookup accesses plus its scan), and the plans the planner picks come out the same. Timings are medians of EXPLAIN (ANALYZE, TIMING OFF) on my laptop, warm cache unless I say otherwise; anything closer than a tenth of a millisecond is noise.
One tenant two hundred times bigger
The lab is sensor readings with the usual lookup tables hanging off them. A site is the tenant, and readings stands in for whichever tenant-scoped table grows fastest in your schema:
CREATE TABLE vendors (id int PRIMARY KEY, name text NOT NULL);
CREATE TABLE models (id int PRIMARY KEY, vendor_id int NOT NULL REFEContributions for week 45
Posted by Cornelia Biacsics in postgres-contrib.org on 2026-11-19 at 11:27
The following speakers delivered sessions about PostgreSQL at PASS Data Community Summit, which happened from 9-11 November 2026:
- Grant Fritchey
- Pat Wright
- David Wagoner
- Ishan Sinha
- Adam Machanic
- Rick Lowe
- Vanshika Nigam
- Amit Arora
On 10 November, the San Francisco Bay Area PostgreSQL Meetup Group met. Korede Aderele delivered a session.
Organizers:
- Katharine Saar
- Stacey Haysler
- Christophe Pettus
On 11 November, the PostgreSQL User Group Vienna met, organized by Cornelia Biacsics & Ranjeet Meghwar. Panagiotis Stathopoulos delivered a talk.
On 12 November, the PostgreSQL Istanbul Meetup met.
Organizers:
- Devrim Gündüz,
- Gülçin Yıldırım Jelínek
- Bilge Korkmaz Erdim
Speakers:
- Devrim Gündüz
- Nazır Bilal Yavuz
On 12 November, the Postgres Meetup for All happened, organized by Elizabeth Christensen. Huseyin Demir delivered a talk.
On 12 November, Gabor Szabo hosted a meetup. David Christensen and Elizabeth Christensen delivered a session.
On 12 November, the London PostgreSQL Meetup Group met, organized by
- Chris Ellis
- Alastair Turner
- Valeria Kaplan
- Michael Christofides
Speakers:
- Greg Clough
- Jonathan Katz
On 13 November, pgDay México 2026 happened.
Organizers:
- Alfredo Rodríguez
- Bryan Camacho
- Carlos Aranibar
- LLibran Martinez
Speakers:
- Bruce Momjian
- Vicky Vergara
- Suman Michael
- Ivan Chavero
- Roberto Luna Rojas
- Anthony Sotongo
- Eduardo Ismael García Pérez
- Sandino Araico Sánchez
Volunteers:
- Abraham Alfaro
- Noel Maye
- Nelly Rodríguez
- José Alfredo Rodríguez
New Security Infrastructure for PostgreSQL
Posted by Andrew Dunstan in EDB on 2026-11-18 at 20:36
Since June 2026, PostgreSQL security fixes have had a home of their own: a private git repository holding every pending fix as a stack of patches, and a private buildfarm that builds and tests that stack across every supported branch, continuously, before anything goes public.
The problem
Security fixes are the one kind of PostgreSQL change that can’t use the normal development process. They can’t be posted to pgsql-hackers, they can’t go into a public commitfest, and they can’t be pushed to postgresql.git and left for the public buildfarm to shake out. They have to stay under embargo until release day.
That left a gap. A fix might be reviewed carefully, but until wrap day it was a patch file passed around among a small group, or stashed in our bug tracker, often with a separate version for each of six or seven branches. Nobody was running it on the range of platforms, compilers and configurations that the buildfarm covers for ordinary commits. Then on wrap day, patches were pushed and the first broad test those fixes got is the public buildfarm, a few hours before tarballs are made.
That’s a lot of risk concentrated in one day, moreover the day when a broken build is most expensive.
The security repository
The core of the new setup is pgsql-security, a private git repository that the security team and committers working on security issues can access. It’s organised as a git quilt: one directory per supported branch, each holding a series file and the patches it lists, in the order they will be applied.
The patches are ordinary git format-patch output, so each carries the author, the commit message and the backpatch information that will end up in postgresql.git. A patch that applies unchanged to several branches can be listed in each branch’s series as a relative path (../master/foo.patch) instead of being copied.
Alongside the quilt, individual fixes in progress can get their own branches, which is where work happens before a fix is ready to join the stack. Work that shouldn’t
[...]PGRX 0.20: Build your own RPM/DEB packages
Posted by damien clochard in Dalibo on 2026-11-18 at 12:30
Writing a Postgres extension in Rust with pgrx is a lot of fun. You write a few functions in Rust, launch an instance with cargo pgrx run and you can call these functions directly inside Postgres.
With cargo pgrx test and cargo pgrx regress, you can run unit tests and regression checks against any major version of Postgres until everything is green. Then comes the last step, and it’s the least fun one: shipping it.
Shipping a PostgreSQL means packages. A lot of packages. One for each distro (RPM/DEB), for each Postgres Major versions and for each CPU architecture. For instance with the PostgreSQL Anonymizer extension, we publish 24 packages for every release…
Until now, the cargo pgrx package command gave you a nice directory tree and politely wished you good luck with the rest. With pgrx 0.20, that last step is gone. :-)
What’s new in pgrx 0.20
But before jumping into that, follow me in a quick overwiew of the new features of PGRX 0.20 which was released a few days ago !
This is a big release, with some breaking changes. Here are the highlights:
- Generated C macros: pgrx now generates automatically Rust versions for all the Postgres C macros and static inline functions at build time. The old hand-written ports are gone, so some code will need an update.
- Postgres 15 to 19: support for Postgres 13 and 14 are dropped, and Postgres 19 is now supported officially
- Safety fixes: several safe APIs that could lead to undefined behavior have been fixed, which changes a few signatures.
-
cargo pgrx migrate: assemble your upgrade scripts from small SQL fragments, one file per change. -
Lighter builds: extensions and
cargo-pgrxitself compile fewer crates, and installingcargo-pgrxon Linux no longer requires the OpenSSL headers. - RPM and DEB packages: the one I want to talk about today!
Packages, Out of the Box
On Linux, cargo pgrx package can now build RPM and DEB files directly:
- No spec file,
- No
debian/folder - No
The hidden costs of CREATE TEMP TABLE: catalog bloat and LWLock:SInvalWrite
Posted by Nikolay Samokhvalov in Postgres.ai on 2026-11-18 at 07:00
Checking a compiler against a second implementation
Posted by salaheddine el hssani on 2026-11-18 at 00:00
A test says what its author expected. When the author also wrote the code, both come from the same reading of the problem, and a mistake in that reading is in both. They agree, the test passes, and the bug ships. Below is one way out of that loop for code whose answers can be computed another way: write a second implementation that is slow and plain, and compare the two on inputs neither author chose. It covers what that comparison found in a policy compiler, what it missed, and why the second implementation needs checks of its own.
The code under test
The code here is a compiler. It reads a short policy ("you may view a folder if it is shared with you, or if you may view its parent") and writes PostgreSQL: views, row-level security policies, closure tables kept current by triggers, functions for single-row checks. That output is built for speed. Inheritance is not walked at query time; a table holds every ancestor of every folder, and triggers move its rows when a folder moves. Each permission can be computed two ways: as a set of ids, for lists, and as a check of one row, for writes. A lookup that another part of the permission already covers is left out.
Each of those choices is a place for a mistake. A closure row not moved on an edge case is a folder someone sees after it moved away. The fast path for lists and the fast path for one row can disagree. A test written against any of them is written by someone who knows what the optimisation was meant to do, and checks that.
The second implementation
The reference evaluator answers the same question with none of those choices. It reads the policy as parsed, not the compiler's model of it, and works on sets of ids in memory. Each relation is a set; each permission is computed from the sets it names. Inheritance is a loop that adds what it finds until nothing changes, a least fixed point. For the folder policy and one user, it comes down to this:
# can view = viewer or parent.view, for one user, as sets of ids
parent = {2: 1, 3: 2, 4: 3,A public safety reminder - large Postgres instances love huge pages
Posted by Kaarel Moppel on 2026-11-17 at 22:00
Distributed primary keys
Posted by Dimitri Fontaine on 2026-11-17 at 15:00
On a single Postgres server, primary keys stay unique because only one sequence hands out the numbers: a bigint identity column asks it for the next one, and no two rows ever get the same. Now put writers in several regions, each of them accepting inserts while the links between them are slow or down. Two regions that each ask their own sequence for “the next number” will hand out the same one, and the first time those two rows meet on a subscriber, one of them is rejected.
So which primary key should we give a table that several regions write at the same time? That’s the question of this article. It continues the logical replication series: Part 1 listed the ways to make ids that can’t collide, and Part 4 built the system that uses them, with a group of nodes in each region and every region subscribed to the others. Here we measure what each choice costs on the same workload: in size, in WAL, in joins, during failovers, and when clocks disagree.
We take the basics for granted. A primary key is a unique and non-null constraint. A generated id is a surrogate key, and it doesn’t replace the natural key, because it can’t stop two rows that describe the same thing. Database Normalization and Primary Keys covers both, and this article is about where the generated id comes from.
TL;DR We compared five primary keys for a table that several regions write at once. A sequence per region is the trap: when a region’s standby is promoted, the sequence can hand out numbers that were already used. uuidv7() is cheap and needs no coordination. A composite (region, id) key lets a publication filter on the region without a second index. A bigint made of a timestamp, the region and a counter does the same with a single column, as long as the clocks agree. And whatever the key, 32 bits is a wall.
PGConf.EU 2026: It's About More Than PostgreSQL
Posted by Jan Wieremjewicz in Percona on 2026-11-17 at 11:00
Autumn is the time when leaves change color and fall. It’s also the time when new PostgreSQL releases come out, or at least that’s been the tradition for quite a while.
There’s one more thing that autumn brings to the PostgreSQL world: PGConf.EU, the annual conference that has grown into the largest PostgreSQL community event.
This year we met in Valencia, Spain. And while I’ve attended several editions already, 2026 brought quite a few firsts for me.
PostgreSQL in Docker for Production: Volumes, Shared Memory, Pooling & Backups
Posted by Aleksei Aleinikov on 2026-11-17 at 06:30
Running PostgreSQL in Docker takes ten seconds to start in development — and about ten minutes to lose data in production if you copy a default compose.yaml snippet from a tutorial.
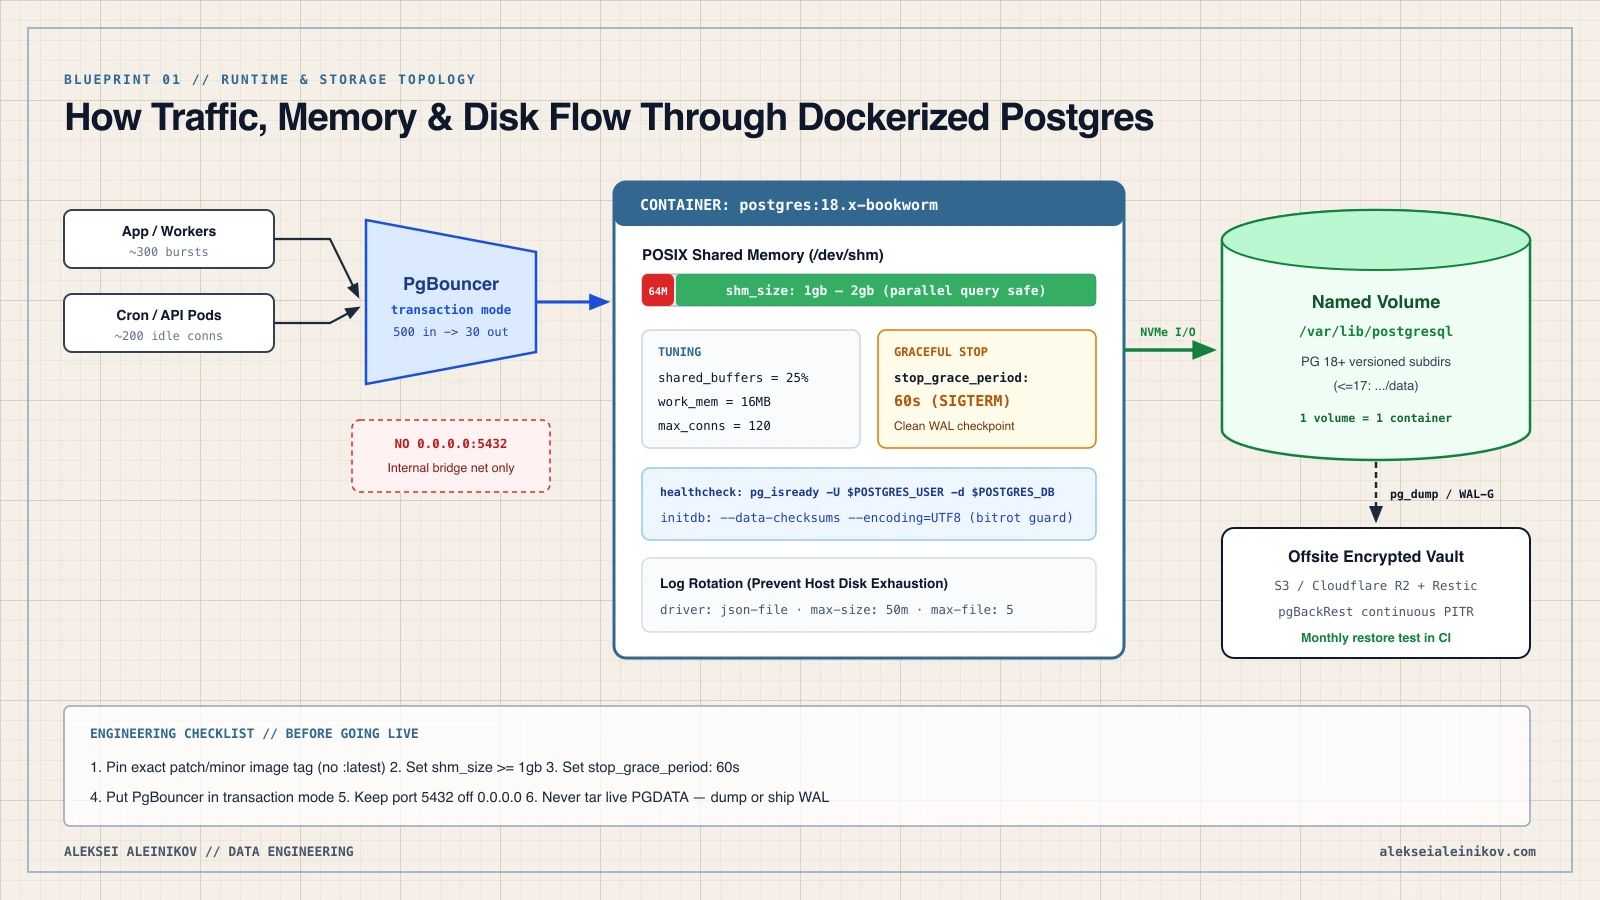
Most outages with containerized Postgres are not caused by Docker itself. They happen because Docker’s defaults (64 MB /dev/shm, a 10-second SIGKILL timeout, unpinned :latest tags, and outdated PGDATA volume paths) collide directly with how PostgreSQL manages memory, checkpoints, and disk files.
The short checklist. Mount PG 18+ volumes at
/var/lib/postgresql(not/data), setshm_size: 1gb+, setstop_grace_period: 60s, enable--data-checksums, put PgBouncer in front of bursts, and never expose port5432on0.0.0.0.
The Breaking Change in PostgreSQL 18+: PGDATA Mount Path
If you upgrade an older Docker Compose stack to PostgreSQL 18 or newer, the very first trap is structural.
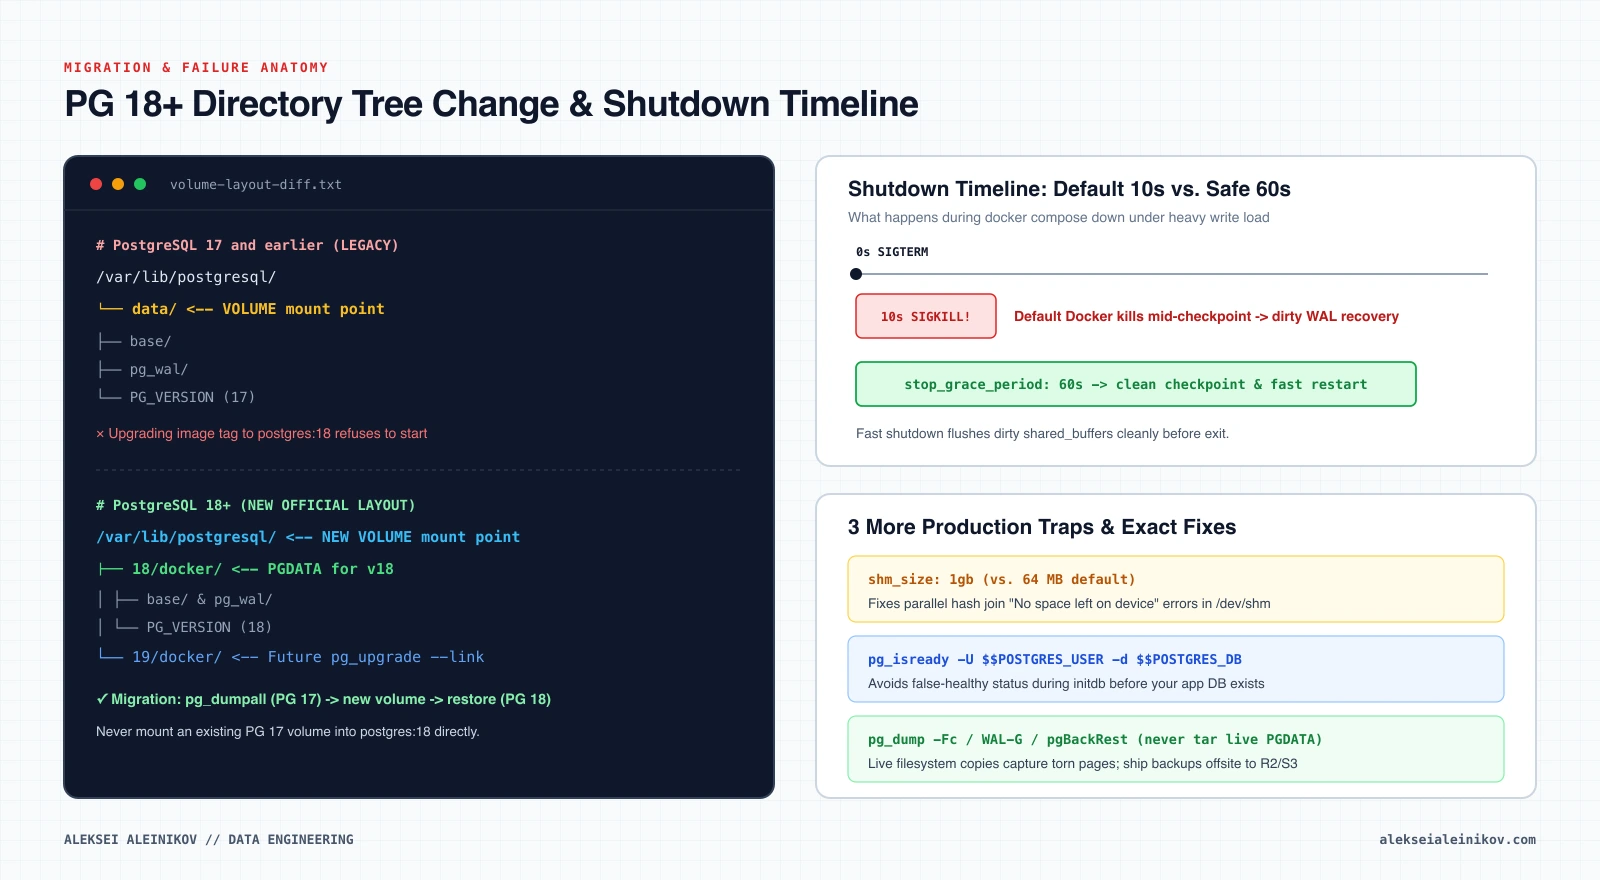
Per the official Docker Hub postgres image documentation:
-
PostgreSQL 17 and earlier:
PGDATAdefaulted to/var/lib/postgresql/data, and Compose files mounted volumes to/var/lib/postgresql/data. -
PostgreSQL 18 and newer:
PGDATAmoved into version-specific subdirectories (/var/lib/postgresql/18/docker, and/19/dockerfor v19), and the officialVOLUMEtarget changed to/var/lib/postgresql.
Why did the maintainers make this breaking change? It aligns the container layout with Debian’s pg_ctlcluster convention so pg_upgrade --link can upgrade major versions cleanly inside the same parent directory in the future.
Working the PgUS Booth at Texas Linux Fest 2026
Posted by Bryan Green in EDB on 2026-11-17 at 04:43
Getting Started With Ollama With DBeaver Community Edition
Posted by Dave Stokes on 2026-11-17 at 01:30
Ollama is popular because it makes running large language models (LLMs) locally simple, private, and inexpensive. DBeaver 26.2.5, also free & open-source, recently added support for Ollama. And both pair well with PostgreSQL.
Why Ollama Is Popular?
-
Runs AI Locally — Execute models such as Llama, Qwen, Gemma, and DeepSeek on your own computer without relying on cloud services.
-
Privacy and Data Control — Prompts and data can remain entirely on your machine, making Ollama attractive for sensitive business information and internal applications.
-
Free and Open Source — Ollama is free to use locally, with no per-token API charges. Individual models have their own licenses.
-
Easy Installation — Download and run models with simple commands:
ollama run llama3.2 -
Developer-Friendly API — Provides a local REST API compatible with many AI development tools, making integration with Python, applications, and databases straightforward.
-
Broad Model Support — Supports numerous open-weight models, allowing developers to experiment with different capabilities, sizes, and performance characteristics.
-
Works Offline — Once models are downloaded, inference can run without an internet connection.
-
Hardware Flexibility — Runs on macOS, Linux, and Windows, supporting CPU inference and GPU acceleration on compatible hardware.
Why Developers Especially Like It
Ollama removes much of the complexity traditionally associated with deploying LLMs. Developers can prototype AI applications, build RAG systems, experiment with AI agents, and implement natural-language-to-SQL interfaces without managing complicated inference infrastructure.
Bottom Line
Ollama has become popular because it makes local AI accessible. It provides a straightforward way to download, run, and integrate powerful language models while retaining control over data, i
[...]pgSherpa: a PostgreSQL companion for your Mac, now on the Mac App Store
Posted by Dinesh Kumar on 2026-11-16 at 23:00
Build, Test and Release Extensions with the New PGXN GitHub Actions
Posted by David E. Wheeler on 2026-11-16 at 20:14
I’ve made three new GitHub actions in the past few months to replace the venerable Docker-based pgxn/pgxn-tools, which has become bloated and requires more work to maintain than I’d like. The new actions require much less maintenance, support all GitHub runner OSes and architectures, and run more quickly. What they do:
- pgxn/postgres-action starts a local, specific version of Postgres server
- pgxn/matrix-action generates a matrix of Postgres versions to test
- pgxn/release-action releases an extension on PGXN
Make a Release
Starting simple, here’s how to use the release action:
name: 🚀 Release
on:
  push:
jobs:
  release:
    name: Release on PGXN
    runs-on: ubuntu-latest
    steps:
        uses: actions/checkout@v7
        uses: pgxn/release-action@v0
        with:
          username: ${{ secrets.PGXN_USERNAME }}
          password: ${{ secrets.PGXN_PASSWORD }}
          dry-run: ${{ !startsWith( github.ref, 'refs/tags/v' ) }}
Yep, that’s it. The pgxn/release-action action will use git archive to create a PGXN bundle and release it on PGXN. (Want to omit some files, such as GitHub workflows, from the release? Use gitattributes to exclude them!) The value passed for the dry-run option prevents publishing the bundle on PGXN except when pushing a Git tag starting with v.
The action also outputs the archive name, so you can use it elsewhere, such as a GitHub release on the last line of this workflow:
name: 🚀 Release
on:
  push:
jobs:
  release:
    name: Release on GitHub and PGXN
    runs-on: ubuntu-latest
    steps:
      - name: Check out the repo
        uses: actions/checkout@v7
      - name: Release on PGXN
        uses: pgxn/release-action@v0
        id: pgxn
        with:
          username: ${{ secrets.PGXN_USERNAME }}
          password: ${{ secrets.PGXN_PASSWORD }}
          dry-run: ${{ !startsWith( github.ref, 'refs/tags/v' ) }}
      - name: Create GitHub Release
        uses: softprops/action-gh-release@v3
if: startsWith( github.ref, 'rinvalid input syntax for type json in PostgreSQL, measured
Posted by Chris van Eijk on 2026-11-15 at 22:30
How to Reduce PostgreSQL Memory Usage and Cut Your Cloud Bill in Half
Posted by Dinesh Kumar on 2026-11-14 at 18:45
Pricing plans in PostgreSQL's currency: pg_orca's PG-aligned cost model
Posted by Jianghua yang on 2026-11-14 at 00:00
Postgres 18.7 Debian and Redhat Packagers Protect You
Posted by Jeremy Schneider on 2026-11-13 at 16:28
Just a short & quick follow-up to [yesterdays blog] before I run out the door.
I hadn’t been paying attention, and yesterday’s postgres release had a few surprises for me. I’m catching up now.
First: read [Devrim’s blog] and [Lukas’ 5-minutes-of-postgres] for the TLDR.
Second: I had this in yesterday’s blog – “RPM packaging now adds a header to require a specific minor. I haven’t checked Debian ecosystem yet but it might also be addressing this.”
I took a quick look this morning, and Debian packaging does have the same protection.
This matters because lots of people won’t upgrade Postgres today (even though we tell them to). Next week they will try to install some new extension, and their OS packager will try to pull the latest version. Devrim and Christoph (two of our primary Postgres packagers  ) have ensured that the packaging systems will protect you from a bad installation.
On Debian:
apt-mark hold postgresql-18
apt-get install -y postgresql-18-cron

Key output (installation fails):
postgres (PostgreSQL) 18.6 (Debian 18.6-1.pgdg12+2)
postgresql-18-cron : Depends: postgresql-18 (> 18.7) but 18.6-1.pgdg12+2 is to be installed
E: Unable to correct problems, you have held broken packages.

...

Allow upgrades:
apt-mark unhold postgresql-18
apt-get install -y postgresql-18-cron
postgres --version

Key output:
The following packages will be upgraded:
  libpq5 postgresql-18 postgresql-18-jit postgresql-client-18
Setting up postgresql-18 (18.7-1.pgdg12+2) ...
Setting up postgresql-18-cron (1.6.8-1.pgdg12+3) ...

...

Package metadata:
apt-cache show postgresql-18-cron

Key output for selected candidate:
Version: 1.6.8-1.pgdg12+3
Depends: postgresql-18 (>> 18.7), libc6 (>= 2.14), libpq5 (>= 9.0~)
On Rocky:
Try unversioned extension installation with PostgreSQL upgrades blocked:
dnf install -y --exclude='postgresql18*' pg_cron_18

Key output (installation fails):
Problem: package pg_cron_18-1.6.8-4PGDG.rhel9.8.x86_64 from pgdg18 requires postgresql18-libs(x86-64) >= 18.7, but Announcing Release 22 of the PostgreSQL Buildfarm client
Posted by Andrew Dunstan in EDB on 2026-11-13 at 15:46
New features
- PGXSExtension module — a single config-driven module for testing
out-of-tree PGXS extensions, keyed by apgxs_extensionshash in the
config (one entry per extension). New test extensions no longer need
their own bespoke.pmfile. The existing BlackholeFDW, FileTextArrayFDW
and RedisFDW modules remain for now so existing configs keep working. - New branches-to-build tags
UNRELEASEDandHEAD_PLUS_UNRELEASED,
covering branches between the time the tree is forked and a release is
tagged. - CheckIndent can now run on any branch that loads it, not just HEAD.
-
localesentries can now be a hashref naming both the locale and the
encoding, e.g.{ locale => 'C', encoding => 'UTF8' }. Encodings are
compared canonically. - Build result submission is retried (up to 5 times, 60 seconds apart) when
the server answers with HTTP 503 "Backend Fetch Failed". - The client version number is now included in the user agent string.
PatchStack improvements
- Apply the patch series with the patches repository's own
import-series.pldriver when present, so the farm tests exactly what a
release wrap produces. Otherwise apply withgit applyrather than
git quiltimport, at full context. - Decide whether a rebuild is needed from the net result of applying the
series, so a branch is rebuilt when a patch it shares from another
branch's directory (e.g.../master/foo.patch) changes. - Resolve symlinked and shared patches via git plumbing.
- New
PGBuild::PatchSeriesmodule for shared series reading, and a new
check_patch_stack.plscript to check a patch stack. - Write a
patch_stack.logfor distinct display on the server. - Optional diagnostic snapshot of repository git state (
diagnose => 1). - Clear stale
git amstate left behind by a failed or killed run, which
previously caused every later run to fail on the first patch. - Don't send the previous run's stage logs when reporting a checkout
failure. - Handle a
PostgreSQL Just Patched 52 CVEs in a Single Minor Release
Posted by Ruohang Feng on 2026-11-13 at 00:00
Build resilient AI workflows with DBOS and Fujitsu Enterprise Postgres
Posted by Greg Nancarrow in Fujitsu on 2026-11-12 at 23:45
Discover how DBOS and Fujitsu Enterprise Postgres combine durable execution, automatic recovery, and robust data encryption to power resilient, secure AI agents and applications, demonstrated through a practical Python deployment.

Postgres 18.7 minor breaks ABI compatibility again
Posted by Jeremy Schneider on 2026-11-12 at 19:12
Postgres API and ABI stability has been a topic of discussion for a long time. To understand why this matters so much, start with Dave Stokes recent blog post [Is PostgreSQL Really Winning Part 2: The Evidence Beyond the Rankings]. It’s fundamentally about “a slow core with a fast edge is a pretty good design” and how the Postgres extension API enables an amazing ecosystem around Postgres.
The official postgres docs have [guidance on API/ABI stability], and for a bit of extra background check out [David Wheeler’s 2024 post-pgconf blog], and EnterpriseDB’s [explainer about the Postgres 17.1 ABI breakage].
The postgres community works really hard not to break ABI compatability because it means that a bunch of extensions won’t interoperate between minors. But sadly this was another of the rare cases where it was needed… this time as a result of CVE-2026-6460 (just one of many CVEs in the GIANT stack that 18.7 contains).
It’s explicit in the release notes and it’s the very first bullet point. https://www.postgresql.org/docs/release/18.7
Introduce versioning logic to permit detection of composite datums that don’t match the tuple descriptor we wish to interpret them with. For full protection, this change requires rebuilding C-language extensions, and there are some extensions that will require source-code changes. If necessary, the new composite_type_mismatch server parameter can be used to disable these checks, but doing so carries security risks.
This will be a pain for Postgres users. It means that extensions (which are packaged and distributed separately) need to be upgraded exactly in lockstep with the Postgres minor bugfix update itself.
One very unfortunate side-effect of the Postgres model: Postgres 18.7 has important CVE fixes – but people using extensions cannot upgrade to 18.7 and get those CVE fixes until their extensions are also updated and have released new extension versions.
I’m doing a lot of work around extensions for CloudNativePG on Kubernetes and I saw a lot of my
[...]Community Over Code Glasgow 2026 and a ColdFront lightning talk
Posted by Jimmy Angelakos on 2026-11-12 at 16:22
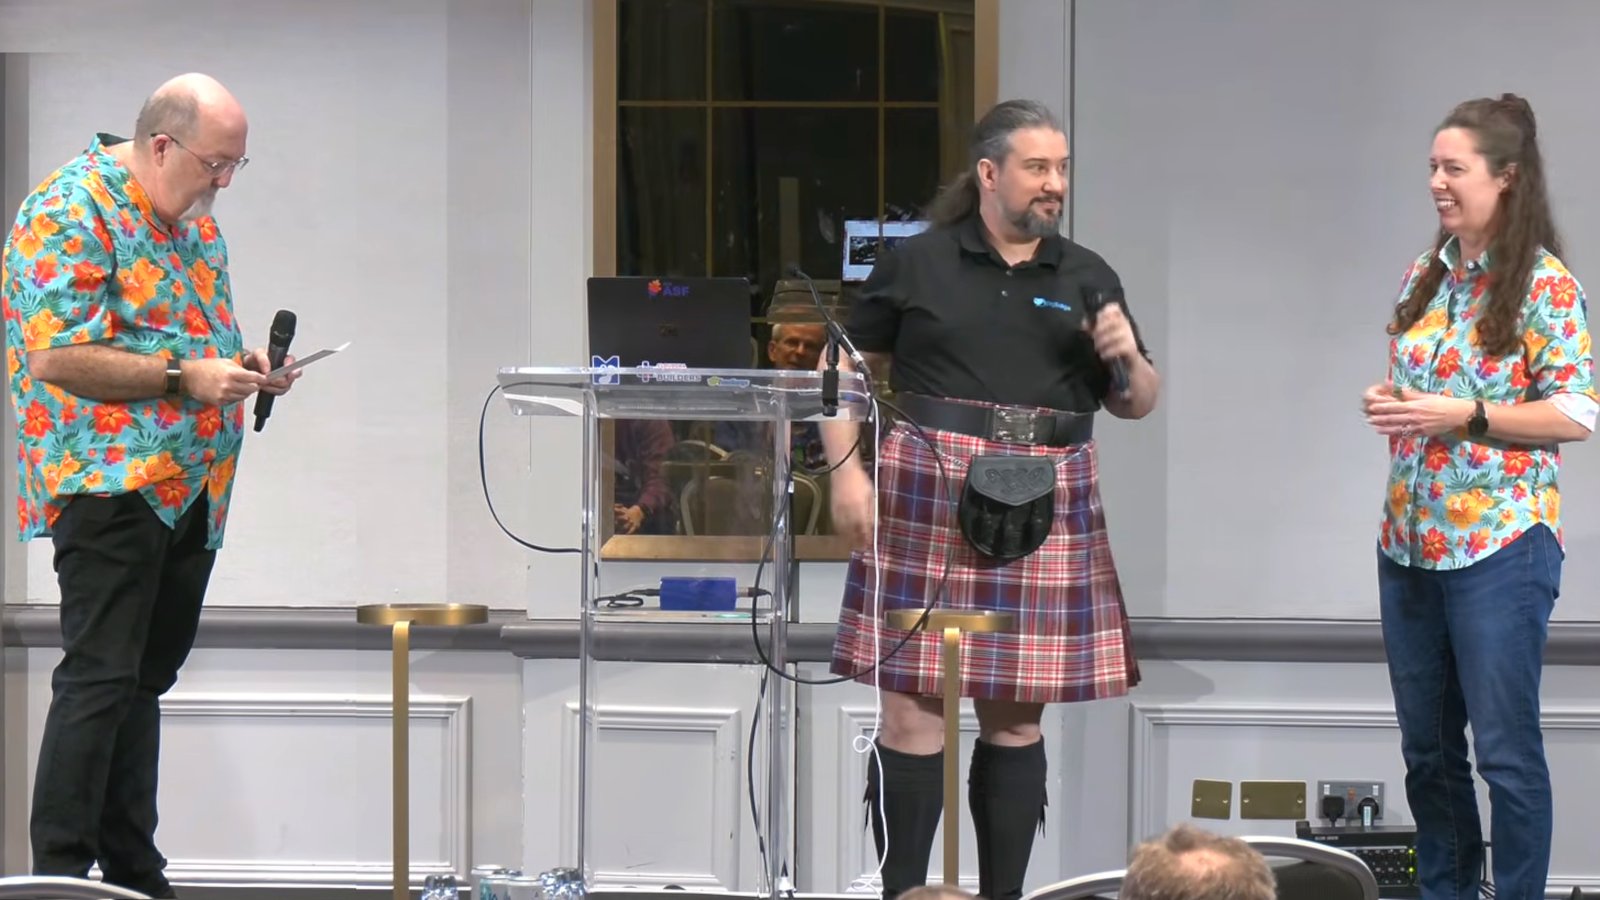
Last month, the Apache Software Foundation's Community Over Code came to Scotland 🏴, taking place from October 11th to 14th at the Hilton Glasgow. Even though I've been in the open source world for 25+ years, this was my first Community Over Code (!), and I loved it: great talks, an amazing hallway track with Apache community rockstars, and a Community track that I very much enjoyed. I also came away convinced that there is huge potential for synergy between the Apache data ecosystem and the PostgreSQL community.
Many thanks to the ASF and everyone who made Community Over Code Glasgow 2026 possible.
The lightning talk: ColdFront
ColdFront didn't exist yet when the Call for Presentations closed, so I submitted it as a lightning talk at the last minute. On Wednesday, October 14th, I had the pleasure of presenting ColdFront: Transparent PostgreSQL Tiering to Iceberg. It was also my first lightning talk under these rules: five minutes, no laptop, no slides! Many thanks to Ruth Suehle and Brian Proffitt of the ASF for hosting.
ColdFront is one example of that synergy: it moves data from PostgreSQL to Apache Iceberg transparently, so your application keeps using plain PostgreSQL. We covered:
- Moving old data that nobody reads to cheaper storage, while keeping it accessible for compliance.
- The UNIX/KISS philosophy, with PostgreSQL as the interface, DuckDB reading and writing Iceberg, and Lakekeeper as the catalog.
- Tiered mode, where older data moves to Iceberg automatically, and decoupled mode, where it lives there from the first row.
- Decoupled storage and compute, so you can scale out reads, and writes too with active-active Spock.
- A writable cold tier, with
UPDATE,MERGE,ALTER TABLEand everything else you would expect, that successfully runs all 99 queries of TPC-DS. - Lamport's bakery algorithm preventing write conflicts between nodes, formally verified in TLA+.
- Vector search for free, using Parquet row group statistics as inverted indexes.
The rec
[...]PostgreSQL November 2026 minor releases: update the server and extensions together
Posted by Devrim GÜNDÜZ in EDB on 2026-11-12 at 12:58
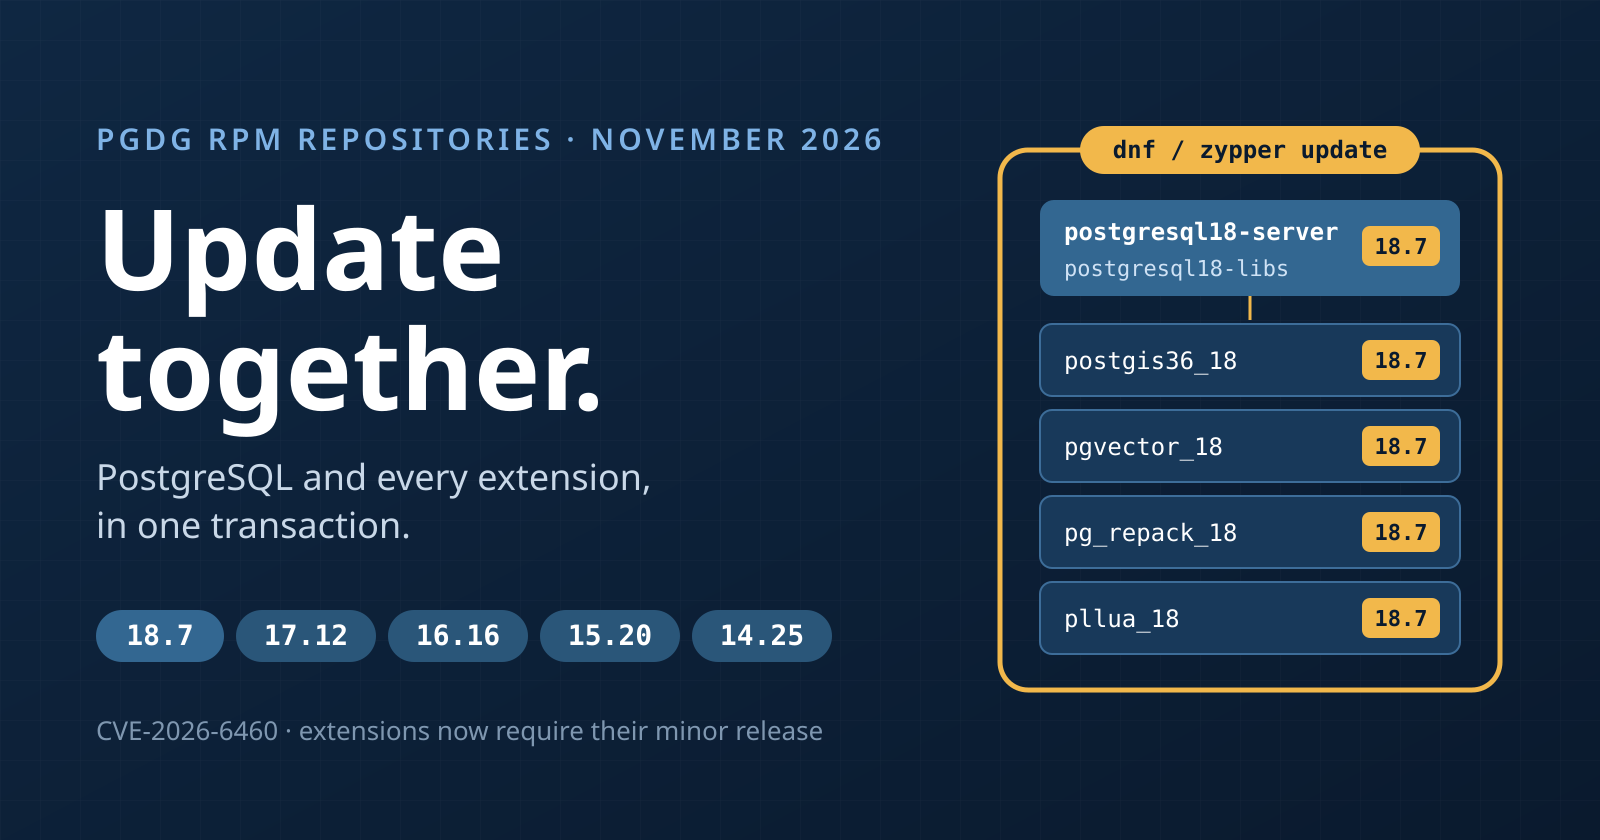
PostgreSQL 18.7, 17.12, 16.16, 15.20 and 14.25 are out today. If you use the PGDG RPM repositories (yum.postgresql.org or zypp.postgresql.org), please update PostgreSQL and all of your extensions in the same transaction this time. Do not update the server today and the extensions next month, and do not hold one back while the other moves.
This release is different from a usual minor release. It contains the fix for CVE-2026-6460, and that fix reaches into the extensions too. So we rebuilt every extension in the repositories against the new minor releases. That covers every package built separately for each PostgreSQL version, on all supported RHEL / Rocky Linux / AlmaLinux, Fedora, Amazon Linux, SLES and openSUSE Leap versions. The rebuilt packages are released together with the new minors.
Why the extensions are tied to the minor release now
The CVE-2026-6460 fix (commit 245eb832f) adds versions for composite types. It changes how composite values are stored, and it changes the server's interface to extensions in two ways:
-
-
DatumGetHeapTupleHeader()used to be a macro. It is now a function in the server. -
-
heap_getattr()now calls the newheap_datum_check(). -
The headers are compiled into the extension, so this affects both directions:
-
- Old extension on a new server: the extension still loads and works. But it does not have the checks of the fix, so it may not be protected from the vulnerability. This is why we rebuilt everything.
-
- New extension on an old server: the extension now calls functions that the old server does not have. It fails to load with an "undefined symbol" error.
-
So a new server needs new extensions to be safe, and the new extensions need a new server to load at all. That is why they have to be updated together.
What changed in the packages
Until now, an extension package only required the PostgreSQL major version. From these rebuilds on, every co
[...]Postgres 18.7 Security Release: The Impact of CVE-2026-6460 & other memory corruption issues
Posted by Lukas Fittl in pganalyze on 2026-11-12 at 12:00
In today’s E123 of “5mins of Postgres” we’re talking about the Postgres 18.7, 17.12, 16.16, 15.20 and 14.25 minor releases that were released today, which fix 52 security vulnerabilities and other bugs in Postgres. In this episode we focus on the security impact of the release, but the release also contains other important fixes.
To help you assess when you should upgrade your system we group the CVEs by what an attacker needs to exploit them, take a closer look at CVE-2026-6460 and its unusually invasive fix, and discuss why this minor release can break extensions and needs extra care when you update your packages.
The quick TLDR: If you’re currently running Postgres and you allow arbitrary SQL to be executed in some way (or SQL injection is a potential concern), you should update to this release. There is a risk that any user who can execute SQL in your database could ultimately become an OS user or the Postgres superuser because of these vulnerabilities.
Share this episode: Click here to share this episode on LinkedIn. Feel free to sign up for our newsletter and subscribe to our YouTube channel.
- Overview of the types of vulnerabilities
- Making sense of 52 CVEs
- Unauthenticated denial of service through cancel requests
- Who can exploit the memory corruption issues?
- CVE-2026-6460: Type confusion with composite types
- Getting a superuser to run the attacker’s SQL
- Compromised remote servers and client tools
- The invasive fix for CVE-2026-6460
Posted by Floor Drees in CloudNativePG on 2026-11-12 at 00:00
Vercel Cron Jobs in Production: Secure, Retry-Safe Jobs with Next.js
Posted by uzair aslam on 2026-11-11 at 22:51
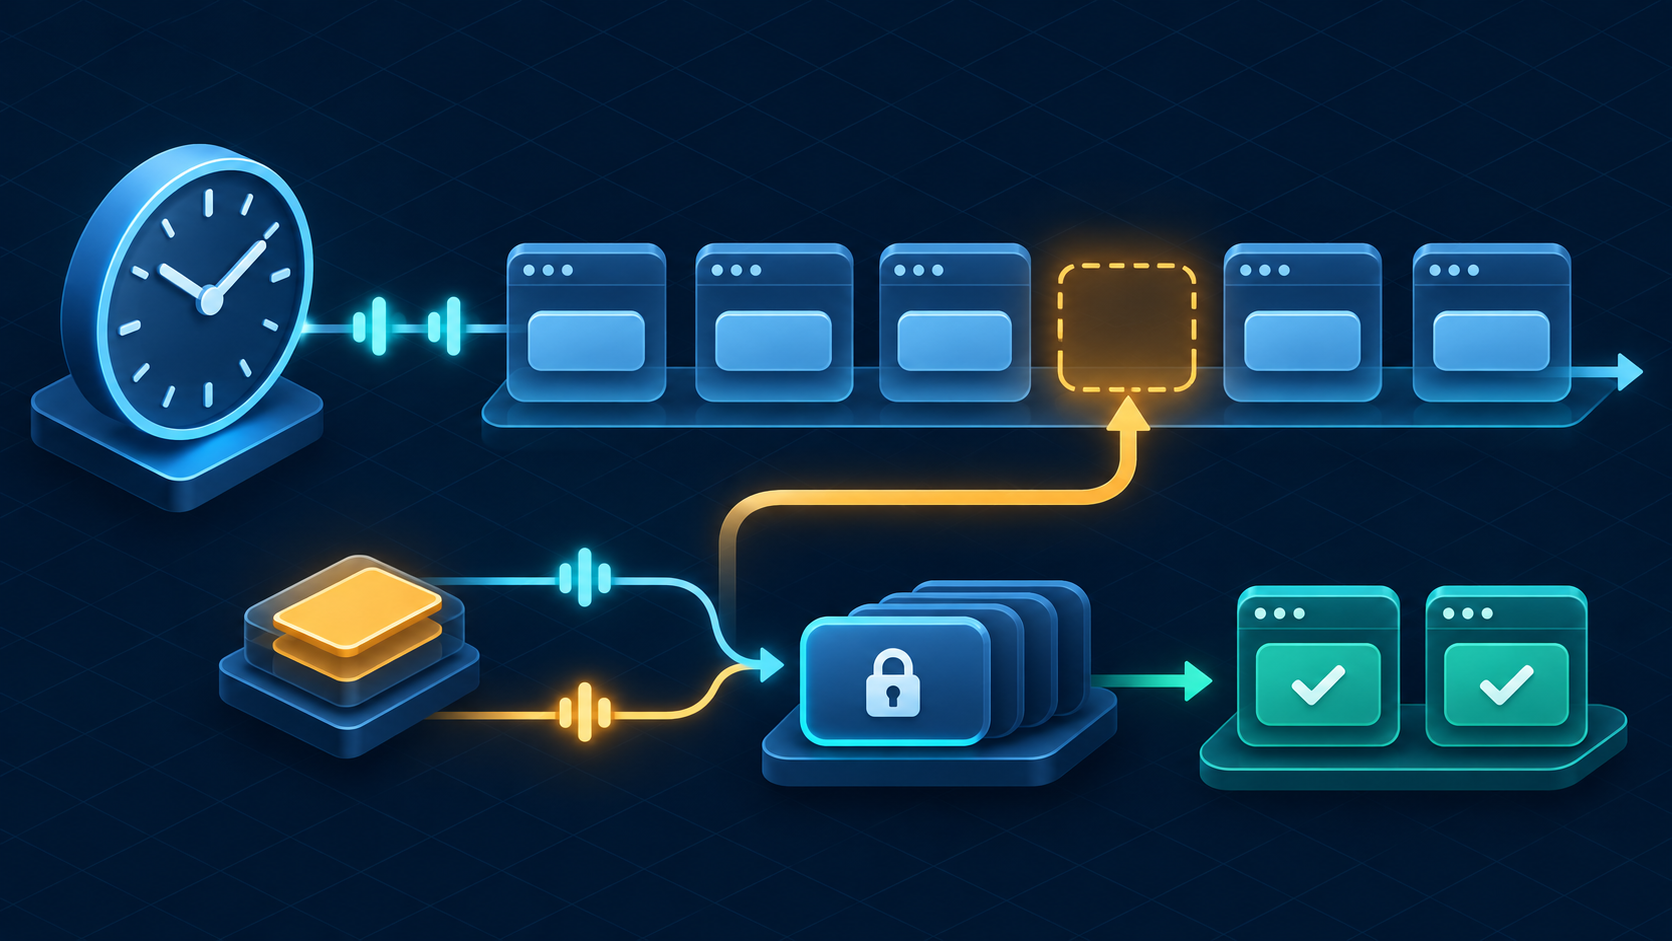
Build Vercel Cron Jobs in Next.js with CRON_SECRET, PostgreSQL locks, bounded backfill, safe retries, and a practical production debugging guide.
Your daily report runs at 02:00 UTC. One morning it never reaches the app. The following day it arrives twice, and both invocations try to produce the same report. A route that processes “today” on each request skips the missing day and may repeat yesterday’s work. The fix is to record which days are due and which were completed in PostgreSQL.
This guide builds a Next.js cron endpoint that queues each closed reporting day once, catches up after missed invocations, and can resume after a crash. The example writes daily event counts to PostgreSQL. A later section explains what changes when a job sends email or calls an external API.
Configure the schedule and protect the route
Vercel Cron Jobs invoke a production route with an HTTP GET on a UTC schedule. Put the configuration in the root directory of the Vercel project. In a monorepo, that is the configured app root, which may differ from the repository root. This example schedules 02:00 UTC daily; the plan limits list minimum intervals and timing precision. A Hobby job may run within the scheduled hour, so do not depend on an exact minute.
{
  "$schema": "https://openapi.vercel.sh/vercel.json",
  "crons": [
    {
      "path": "/api/cron/daily-report",
      "schedule": "0 2 * * *"
    }
  ]
}
Set a random CRON_SECRET in Production. Vercel sends it as a Bearer token. Fail closed if the variable is missing, and never log the header. The cron management docs explain how deployed environment values, rotations, and rollbacks interact. After changing the value, deploy and verify the next invocation.
A request that reaches the route is a wake-up signal. It can be late, duplicated, or absent; Vercel does not retry a failed cron invocation. The delivery guidance recommends reconciliation. Keep the schedule as a trigger and put the actual reporting state in the database.
Model a
[...]Top posters
Number of posts in the past two months
 Christophe Pettus (pgExperts) - 54
- Chris van Eijk - 39
- Devrim GÜNDÜZ (EDB) - 10
- Vadim Yatsenko (Awide Labs) - 9
- Ruohang Feng - 8
- Cornelia Biacsics (postgres-contrib.org) - 8
- Radim Marek - 6
- Hollis Varden - 6
- Igor Suhorukov - 6
- Mats Kindahl - 6
Top teams
Number of posts in the past two months
- pgExperts - 54
- EDB - 24
- Awide Labs - 9
- pgEdge - 9
- Stormatics - 8
- postgres-contrib.org - 8
- Percona - 5
- Postgres Professional - 4
- ClickHouse - 4
- Cybertec - 3
Feeds
Planet
- Policy for being listed on Planet PostgreSQL.
- Add your blog to Planet PostgreSQL.
- List of all subscribed blogs.
- Manage your registration.
Contact
Get in touch with the Planet PostgreSQL administrators at planet at postgresql.org.